Projects

Software engineering 4 projects

Browser Plugin for JabRef · University software project

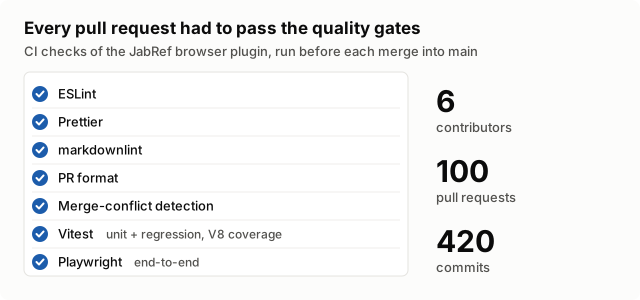
  • Established quality gates in a 6-person team with 5 GitHub Actions workflows (ESLint, Prettier, markdownlint, PR format, merge-conflict detection), stopping style and format defects before the merge into main.
  • Built the test automation from scratch with Vitest (unit and regression tests, V8 coverage) and Playwright (end-to-end), chosen via MADR after evaluating 4 frameworks and run in CI on every pull request.
  • Wrote the Quality Management Plan (Definition of Ready/Done, GitHub Flow, test methods), adopted by all 6 contributors across 100 pull requests and 420 commits.
JavaScript Vitest Playwright ESLint Prettier GitHub Actions OpenFastTrace MADR
CI checks run on every pull request: ESLint, Prettier, markdownlint, PR format, merge-conflict detection, Vitest unit and regression tests, Playwright end-to-end tests; 6 contributors, 100 pull requests, 420 commits

Qwixx Scoreboard

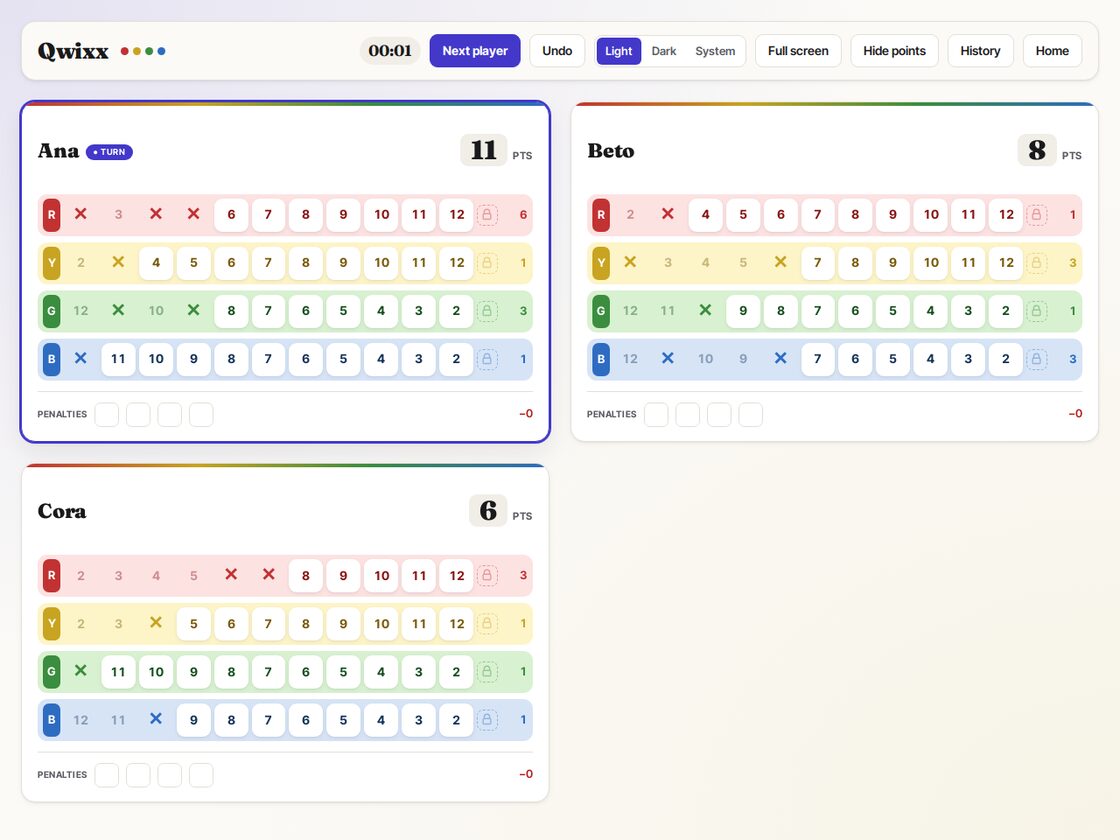
  • Live-synced digital scoreboard for the Qwixx dice game, built spec-first and tested with Playwright, axe-core and bun test.
TypeScript Bun React Server-Sent Events Playwright
Qwixx scoreboard with three players, each with red, yellow, green and blue rows of crossed-out numbers and a live point total

LSF Grade Finder

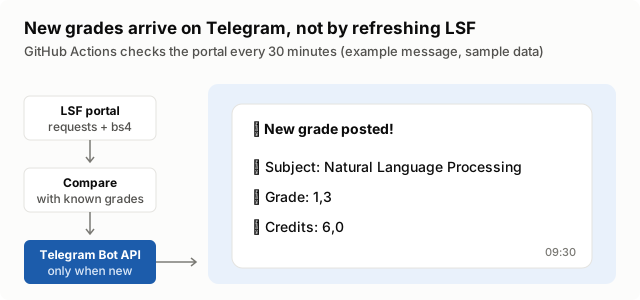
  • Telegram notifications for new grades on the Universität Hildesheim LSF portal.
Python requests BeautifulSoup pytest GitHub Actions
Pipeline from the LSF portal to a comparison with known grades to the Telegram Bot API, with an example message: New grade posted, subject, grade and credits

Automated Flat Search

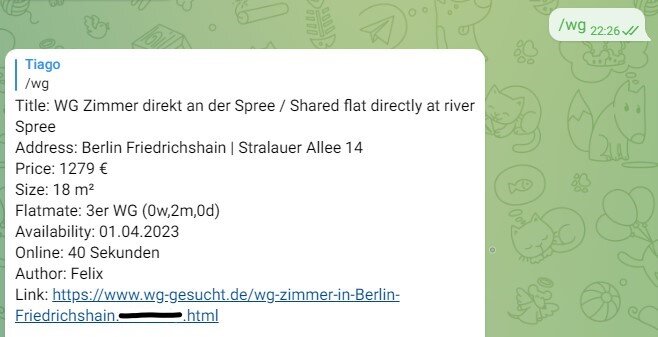
  • Scrapes WG-Gesucht and sends real-time notifications about new listings through a Telegram bot.
Python MySQL Heroku Telegram API Dash Plotly
Telegram bot message for a new WG-Gesucht listing in Berlin Friedrichshain with title, address, price, size, flatmates, availability and link

Academic research 2 papers

NLP course paper

LLM Prompting vs. fastText for Text Classification

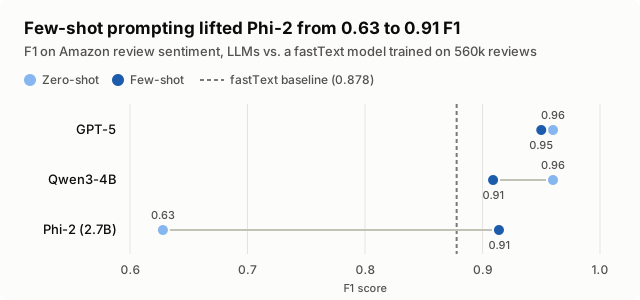
Compared zero-shot and few-shot prompting of Qwen3-4B, Phi-2 and GPT-5 against a fastText baseline trained on 560,000 Amazon reviews. Every few-shot model beat the baseline, and few-shot prompting lifted Phi-2 from 0.63 to 0.91 F1.

Python Hugging Face Transformers fastText scikit-learn pandas prompt engineering
F1 scores: Phi-2 rises from 0.63 zero-shot to 0.91 few-shot, Qwen3-4B 0.96 zero-shot and 0.91 few-shot, GPT-5 0.96 zero-shot and 0.95 few-shot, fastText baseline 0.878

B.A. thesis · ACL submission (not accepted)

Topic Modeling of Brazilian YouTube Comments on COVID-19

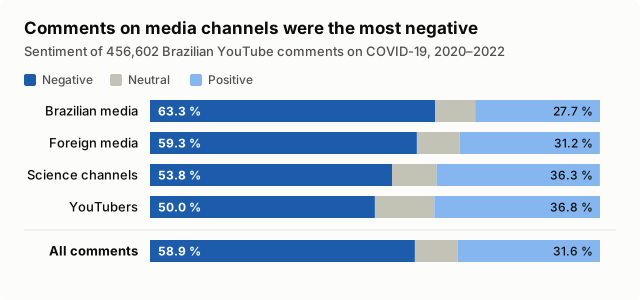
Collected 456,602 Portuguese comments from 2,604 videos on 37 channels with the YouTube Data API and modelled them with BERTopic and LeIA sentiment analysis. Audiences of scientists’ channels discussed vaccines and prevention, media audiences discussed politics, and 58.9 % of all comments were negative.

Python YouTube Data API v3 spaCy BERTopic Sentence-Transformers LeIA pandas
Share of negative comments by channel group: Brazilian media 63.3 %, foreign media 59.3 %, science channels 53.8 %, YouTubers 50.0 %, all 456,602 comments 58.9 %